Learning about ML training with the NVIDIA Workbench Example Kaggle Competition Kernel
Get link
Facebook
X
Pinterest
Email
Other Apps
Kaggle runs different machine learning or data science competitions. You can participate using their containerized environments or by coding locally. NVIDIA simplified working locally, or in your own cloud, with an AI Workbench-compatible example Kaggle competition kernel. Their project contains everything needed to download competition data from Kaggle, run train/test cycles, and then upload the results for evaluation. I love this dockerized project because it lets me play in a competition sandbox on my local machine with no local configuration changes to my development machine
The Handwritten Digits Recognizer competition is an open-ended competition trainer. Kaggle provides images of handwritten digits. You train against the training dataset and test against the testing dataset. Then run your trained model against the candidate digits of the competition submission set and upload the results to the Kaggle competition.
The NVIDIA Workbench example Kaggle competition kernel is designed around the Kaggle competition workflow and is built on top of Kaggle-created GPU-enabled Docker images. It contains an input data Jupyter Notebook, a Processing Notebook, and a Competition Submission Notebook. You configure the contest name in the first one to download the data and then create, train, and test your model in the 2nd Jupyter Notebook. Lastly, the 3rd Notebook is used to package and upload the results of the competition dataset analysis. The project is set up to let you change competitions and change the processing used to train the model.
Parameter Tuning
Model training is done by tuning the model parameters while consuming the testing data. Training is computationally intensive, requiring another run for each training parameter change. This.is the biggest computational task, one that can be well-suited to GPU parallelization. This diagram shows the accuracy adjustments in the training and test data set as the parameters are adjusted. We will look at the training computational cost below.
Digits Competition
The source images are sized 28x28. A sample set of digits at the model resolution to the right.
I erroneously said in the video that.
The sample project scales down the images to speed up the training and analysis process.
That was incorrect
Micro benchmarking GPU vs GPU vs CPU
NVIDIA Workbench example Kaggle competition kernel supports both GPU-based and CPU-based training and execution. It will automatically use any GPUs available to the containers. The container falls back to CPU execution when no GPU is available. The A600 timing is in the project documentation. The rest of the timing was generated on my machines. Processing on a GPU is significantly faster than CPU processing with a CPU. The time difference grows proportional to the size of the data sets and the resolution of the images. The test data only contains 30 images. There are 20 training iterations.
Processor
RTX A6000
Titan RTX
RTX 3060 TI
Ryzen 5900X
Xeon E5-2680 V2
Wall time
20 sec
40 sec
65 sec
386 sec
419 sec
Cuda Cores
10752
4608
4864
Tensor Cores
336
576
152
Tensor Gen
3
2
3
SM
84
72
38
Tensor Cores
SM * 4
SM * 8
SM * 4
FP16 (TFLOP)
38.7
32.6
16.2
FP32 (TFLOP)
16.3
16.2
FP64 (GFLOP)
509
253
Cores (c/t)
12/24
20/40
CPU
3.7 Ghz
2.8 Ghz
CPU Time (HH:MM)
1:36:00
2:55:00
Training consumed about 600MB of VRAM. These timings illustrate the computational expense of training. The Xeon machine run consumed 65% of all 40 Xeon cores for 7 minutes of wall time, resulting in 3 hoursof aggregated CPU time.
Train and Test used above
This one line of code ran the train and test cycle.
history=model.fit(X_train,Y_train,
epochs=20,batch_size=64,
validation_data=(X_dev,Y_dev)
)
The training run output can be seen here. You may need to click on it.
Switching between CPU and GPU in the Kaggle Container
I brute force to make the GPU available or unavailable. Setting "0" GPUs forces CPU execution. Any other value makes a GPU available for execution. This requires a restart for the container to pick up the change.
The competition name is sourced from a variable. It defaults to the Kaggle Handwritten Digits Recognizer. You can change the variable to point at a different competition.
Kaggle Secrets
Kaggle competitions require registration and the generated keys. You can set the Kaggle credentials in the AI Workbench Environment tab.
Input and Output File Locations
The project lets you store the downloaded input files and the generated output to a location outside of the containerized environment through the use of Host Mounts. The screenshot below configures a Windows/WSL machine to store the files on the Windows D drive.
Discussing performance
Making the input and output directories
Putting this here is more for me than other folks so I don't forget what I did.
Windows WSL
We want the competition input and output files hosted locally on a Windows drive where they will persist even if we destroy the competition container and then rebuild it. In this case, I wanted them on D:/kaggle/input. The Windows file systems are mounted to the container under /mnt/ so we end up with /mnt/d/kaggle/input and /mnt/d/kaggle/output.
I hopped into the workbench WSL environment to create the directories with bash. It could just as well have been done in Windows with PowerShell.
We do the same thing for a Linux environment. I ran this on a remote Linux machine where I ran a remote version of the AI Workbench. In this case, I put the two Kaggle directories in /tmp
You download GitHub code by "cloning" the repository to a local repository. They call this a desktop clone. Each GitHub repository home page has a neat "Clone to Desktop" button in the web interface that you would think clones the repository to your desktop. That button actually takes you to the GitHub Windows application download page even if you have the GitHub app already installed. This is where I usually get stuck and head off to some search engine for help. The Windows GitHub application tries to tell you what to do at the bottom of the "local repository" screen. It says to "Drag a repository here to add". That phrase always confused me. I can never figure out where to drag the repository from. It turns out you are supposed to drag the URL for the repository from your browser onto the desktop application. Resize your browser window so you can drag the repository onto the GitHub windows application. ...
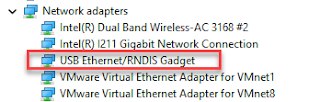
I do a lot of my development and configuration via ssh into my Raspberry Pi Zero over the RNDIS connection. Some models of the Raspberry PIs can be configured with gadget drivers that let the Raspberry pi emulate different devices when plugged into computers via USB. My favorite gadget is the network profile that makes a Raspberry Pi look like an RNDIS-attached network device. All types of network services travel over an RNDIS device without knowing it is a USB hardware connection. A Raspberry Pi shows up as a Remote NDIS (RNDIS) device when you plug the Pi into a PC or Mac via a USB cable. The gadget in the Windows Device Manager picture shows this RNDIS Gadget connectivity between a Windows machine and a Raspberry Pi. The Problem Windows 11 and Windows 10 no longer auto-installs the RNDIS driver that makes magic happen. Windows recognizes that the Raspberry Pi is some type of generic USB COM device. Manually running W indows Update or Upd...
Entity resolution decides whether two listings from different sources describe the same real-world business. The listings share no key, and their names and addresses rarely match letter for letter. The same problem turns up in customer master data, supplier deduplication, provider directories and fraud detection. entitopia is an open-source project for this kind of matching on Elasticsearch. It keeps everything specific to a dataset in JSON configuration. One sample project reads the US register of motor carriers, about 2.1 million companies. It looks for carriers that a regulator shut down and that may have reopened under a new name. A second sample project looks for duplicate listings among 5,419 Medicare hospitals. Use Elasticsearch to match businesses measures how to compare each field. Tuning an entity matcher measures what the candidate search and the ignored values let the scorer see. This article covers what it took to run the same matche...


 Parameter Tuning
 Digits Competition