Creating order out of chaos in a world of AI Everywhere
Get link
Facebook
X
Pinterest
Email
Other Apps
The hot ticket right now is "Put AI Everywhere". This usually results in a race to come up with ideas about how AI can be used in new products or existing systems. I suggest creating a system to analyze existing processes, software, and programs with a structured approach, identifying opportunities and assessing risks and rewards.
LLM agents, chat bots and instructors models that turn human speech and writing patterns into content or actions is in scope here. TTS, STT, translators and other non integrated LLM uses are out of scope.
The talk below iteratively breaks down our process until we reach the point where we identify AI opportunities. We start with PDCA (Plan-Do-Check-Adjust) as a notion for the lifecycle of products, software, and processes. We can map that into the following in the software space. Item 4 could be anything specific to your domain.
Design Time: All of the processes that happen before actual code execution. This is before transactions, customer interactions, or electrons fired at customer problems. This is a target of opportunity. There is a lot of work in this phase with points for human oversight. No one dies in this phase.
Run Time: For software, this is the deployed application. For manufacturing, this would be the actual manufacturing process. The "run" operates only with after-the-fact oversight. This is the riskiest phase if we let the ML make decisions, make offers, or call services that change data.
Analytics: This is the equivalent of "Check". It is where we observe the run phase, teasing out details for the next design spin.
Everything Else: This should be "Adapt" or "ACT" in the PDCA. I'm using it as a placeholder for things that don't fit in Design Time, Run Time, or Analyze/Check. In my case, that is manipulation, where we modify information out of band to the mainline process.
Design Time (Plan and Build)
Design time spans a range of functions and opportunities, anything prior to being put into production or exposed to the business or operations. Examples include requirements gathering or generation, requirements document generation, human to DSL conversion, rule conversion, code generation, validation (test) generation. Plugging AI into design time injects LLMs into converting or extracting documents. Design time has the upside of providing places for human oversight, a good idea at the current level LLM capabilities.
Run Time (Execute)
This is putting LLMs inside the unattended customer-system interaction loop with the LLM touching customer data, querying for data or making decisions and changes on a customer’s behalf based on the LLMs interpretation of the request. This is probably the riskiest way of using an LLM especially if it is integrated with data stores or operational systems. Incorrect usage in this area can lead to significant reputational and regulatory risk.
LLMs are not idempotent returning different answers to the same question meaning different users get different responses for the same problems. This can be problematic if it causes the LLM to make different requests to the backend for the same message. It can be difficult to lock down LLMs opening the company up to prompt injection and other attacks that can be significantly harder to recognize that something like SQL injection attacks.
Chat bots are the public face of LLM run-time usage. There is an entire industry around enabling, armoring and controlling chat bots. An insecure chatbot plugged into backend systems can be a great business tool or an unexpected public portal to backend systems.
LLMs in the run loops can be 10x more expensive than other solutions where other good solutions exist. Non LLM solutions have often been through tuning processes. This means the LLM has to be a lot better than other solutions to be in the run loops.
Image generation as a product
Image generation doesn’t fit the Design-Time / Run-Time model. The LLM output is the product. Manual image generation could be considered run-time with publishing and usage being the run time components. Human driven image generation provides some safety net. Unattended image generation and publishing comes with the same reputational risk as other run-time scenarios.
Analytics
Analytics can be used to generate automated responses and remediation or to create action items for humans. Automated LLM remediation has the same risks “inside the run loop” risks discussed above. LLM automated actions is like putting a junior team member on the night shift with their hand on the big red button. You are going to need a lot of testing and training to make it safe. LLM driven alerts and dashboards is the on ram for investing the analytics area with LLMs.
Business reports fall into this space also. Current reporting tools probably provide a more stable traceable way of generating reports. Maybe LLMs work for intuitive insights if you don’t mind getting different answers for the same data when you un-leash the LLM.
Other (Adjust, Manipulate, etc)
There is a whole space of problems that have long sets of error prone instructions. Data conversion failures, data fixing for processing errors can be expensive to fix or to rollback. LLMs may be able to operate in this space as reliably as many auditors or business users if a proper hint set can be generated and a standardized prompt style created.
You download GitHub code by "cloning" the repository to a local repository. They call this a desktop clone. Each GitHub repository home page has a neat "Clone to Desktop" button in the web interface that you would think clones the repository to your desktop. That button actually takes you to the GitHub Windows application download page even if you have the GitHub app already installed. This is where I usually get stuck and head off to some search engine for help. The Windows GitHub application tries to tell you what to do at the bottom of the "local repository" screen. It says to "Drag a repository here to add". That phrase always confused me. I can never figure out where to drag the repository from. It turns out you are supposed to drag the URL for the repository from your browser onto the desktop application. Resize your browser window so you can drag the repository onto the GitHub windows application. ...
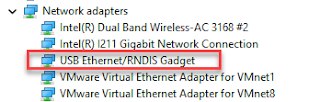
I do a lot of my development and configuration via ssh into my Raspberry Pi Zero over the RNDIS connection. Some models of the Raspberry PIs can be configured with gadget drivers that let the Raspberry pi emulate different devices when plugged into computers via USB. My favorite gadget is the network profile that makes a Raspberry Pi look like an RNDIS-attached network device. All types of network services travel over an RNDIS device without knowing it is a USB hardware connection. A Raspberry Pi shows up as a Remote NDIS (RNDIS) device when you plug the Pi into a PC or Mac via a USB cable. The gadget in the Windows Device Manager picture shows this RNDIS Gadget connectivity between a Windows machine and a Raspberry Pi. The Problem Windows 11 and Windows 10 no longer auto-installs the RNDIS driver that makes magic happen. Windows recognizes that the Raspberry Pi is some type of generic USB COM device. Manually running W indows Update or Upd...
Entity resolution decides whether two listings from different sources describe the same real-world business. The listings share no key, and their names and addresses rarely match letter for letter. The same problem turns up in customer master data, supplier deduplication, provider directories and fraud detection. entitopia is an open-source project for this kind of matching on Elasticsearch. It keeps everything specific to a dataset in JSON configuration. One sample project reads the US register of motor carriers, about 2.1 million companies. It looks for carriers that a regulator shut down and that may have reopened under a new name. A second sample project looks for duplicate listings among 5,419 Medicare hospitals. Use Elasticsearch to match businesses measures how to compare each field. Tuning an entity matcher measures what the candidate search and the ignored values let the scorer see. This article covers what it took to run the same matche...