Python has become one of the most popular application languages in IT, shadow-IT, and data science. Python developers continually improve their systems by iterating from example patterns to best practices.
The Python logging package should be used wherever print() statements were in the past. The logging package makes it possible to classify output at different severities. logging has the ability to enable and disable the generation of output at those different levels. This means you can create debug-level statements that are useful to programmers without letting those statements bleed into a production application. The referenced GitHub project shows how to load logging configurations, and how to change where logging goes based on those configurations.
Classify output by severity
Filter output generation by severity
Send data to different sinks based on the program module and the severity
Logging Design
Logging is routed through loggers that are instantiated in each python module. Those loggers are configured with one or more handlers. Each handler writes to its own log sink based on the filter criteria it was initialized with. This means a log message can be written out by 0 or more handlers depending on the logging level of the message and the filter message of the handlers.
Watch the video or read the Python logging documentation for an explanation of how levels work. I'm too tired to write it up right now.
Our log output format, handler configurations, and logger configurations are all stored in a yaml file. This file shows a variety of formatters and handlers. It contains a custom configuration for each python module that intends to log. Small programs can probably just run with the console logger and the root configuration. Larger or production programs will probably have something more detailed like this example.
The logging module must be initialized one time. Here we have a function that we can call on program startup to initialize the logging configuration.
importlogging
importlogging.config
importyaml
defload_logging():
withopen("logging_config.yaml", "r") asf:
config = yaml.safe_load(f.read())
logging.config.dictConfig(config)
Creating a logger in main()
Load the logging module one time on startup. Here we demonstrate loading the config at the top of main()
importlogging
fromloggingconfigimportload_logging
def main():
load_logging()
logger = logging.getLogger(__name__)
Creating a logger in a Multi-processor Class
Each python file will need access to a logger. The sample program is a bunch of multi-processing modules. We can create a logger in the __init__() function. Non-class python files can just do it at the top.
Non-class python files also need to create a logger. In this case the module will actually be __main__ . Note that this example shows both initializing the logging system and creating the logger for this file.
if__name__ == "__main__":
load_logging()
logger = logging.getLogger(__name__)
Logging a message and deferring string construction
It is very important that you do not pre-construct logging strings. The logger will format the logging string only if the message is actually going to be sent to one of the sinks. A log of logging, especially debug(), will never make it past the handlers. The type of string formatting shown below will insure that the debug() log strings would never be created in those situations.
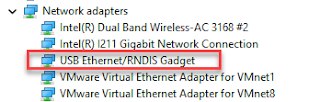
I do a lot of my development and configuration via ssh into my Raspberry Pi Zero over the RNDIS connection. Some models of the Raspberry PIs can be configured with gadget drivers that let the Raspberry pi emulate different devices when plugged into computers via USB. My favorite gadget is the network profile that makes a Raspberry Pi look like an RNDIS-attached network device. All types of network services travel over an RNDIS device without knowing it is a USB hardware connection. A Raspberry Pi shows up as a Remote NDIS (RNDIS) device when you plug the Pi into a PC or Mac via a USB cable. The gadget in the Windows Device Manager picture shows this RNDIS Gadget connectivity between a Windows machine and a Raspberry Pi. The Problem Windows 11 and Windows 10 no longer auto-installs the RNDIS driver that makes magic happen. Windows recognizes that the Raspberry Pi is some type of generic USB COM device. Manually running W indows Update or Upd...
Your content is only as good as it presents 💬 I've had plenty of blog articles that I thought were good enough to put out on the Internet. It was only after I tried to use them as a basis for a video that I realized how chaotic or incomplete they were. AI-Assisted Timeline 2 hours wall clock getting an LLM to create outlines for 6 blog articles 1 hour to generate a blog article from the outline 2 wall clock hours of iteration and ideation and proofreading 4 days of coffee decompression Return to project 6 wall clock hours of iteration with the AI and proofreading Published the article. Immediately found problems 2 wall clock hours of iteration and republished 1 day later LLM found problems while working on other article. 1 wall clock hour of proofreading and iteration 4 days of other stuff including coffee decompression Started video recording Unrecorded hours of swearing 1 wall clock hour of iteration and republished Unrecorded hours of moaning and banging head on table. 2 wall ...
This article was revised with later test data. Earlier figures and tables on this page were replaced. Each Ollama runner keeps a prefix cache that can skip re-evaluating a shared system prompt. Nine of seventeen local builds reused the cached system prompt on nearly every new conversation. Four others re-evaluated a 1,024-token batch of it each time. Four more re-evaluated all of it once per system prompt, up to 37 seconds on the largest. The model's memory type and runner set the group, not the prompt. In freemansoft/Flutter-AdaptiveCards a demonstration Dart chat server asks a local Ollama model for an answer as Adaptive Card JSON. That is a strict, closed-vocabulary schema, which a Flutter app renders as interactive UI. The card system prompt that describes the element vocabulary runs to about 3,800 to 4,400 tokens, by the model's tokenizer. The chat server replays up to ten prior exchanges on every turn. Each Ollama runner keeps a prefix cache, so a request whose open...